6 min read
Plan once, ground locally: 83.6% fewer agent tokens
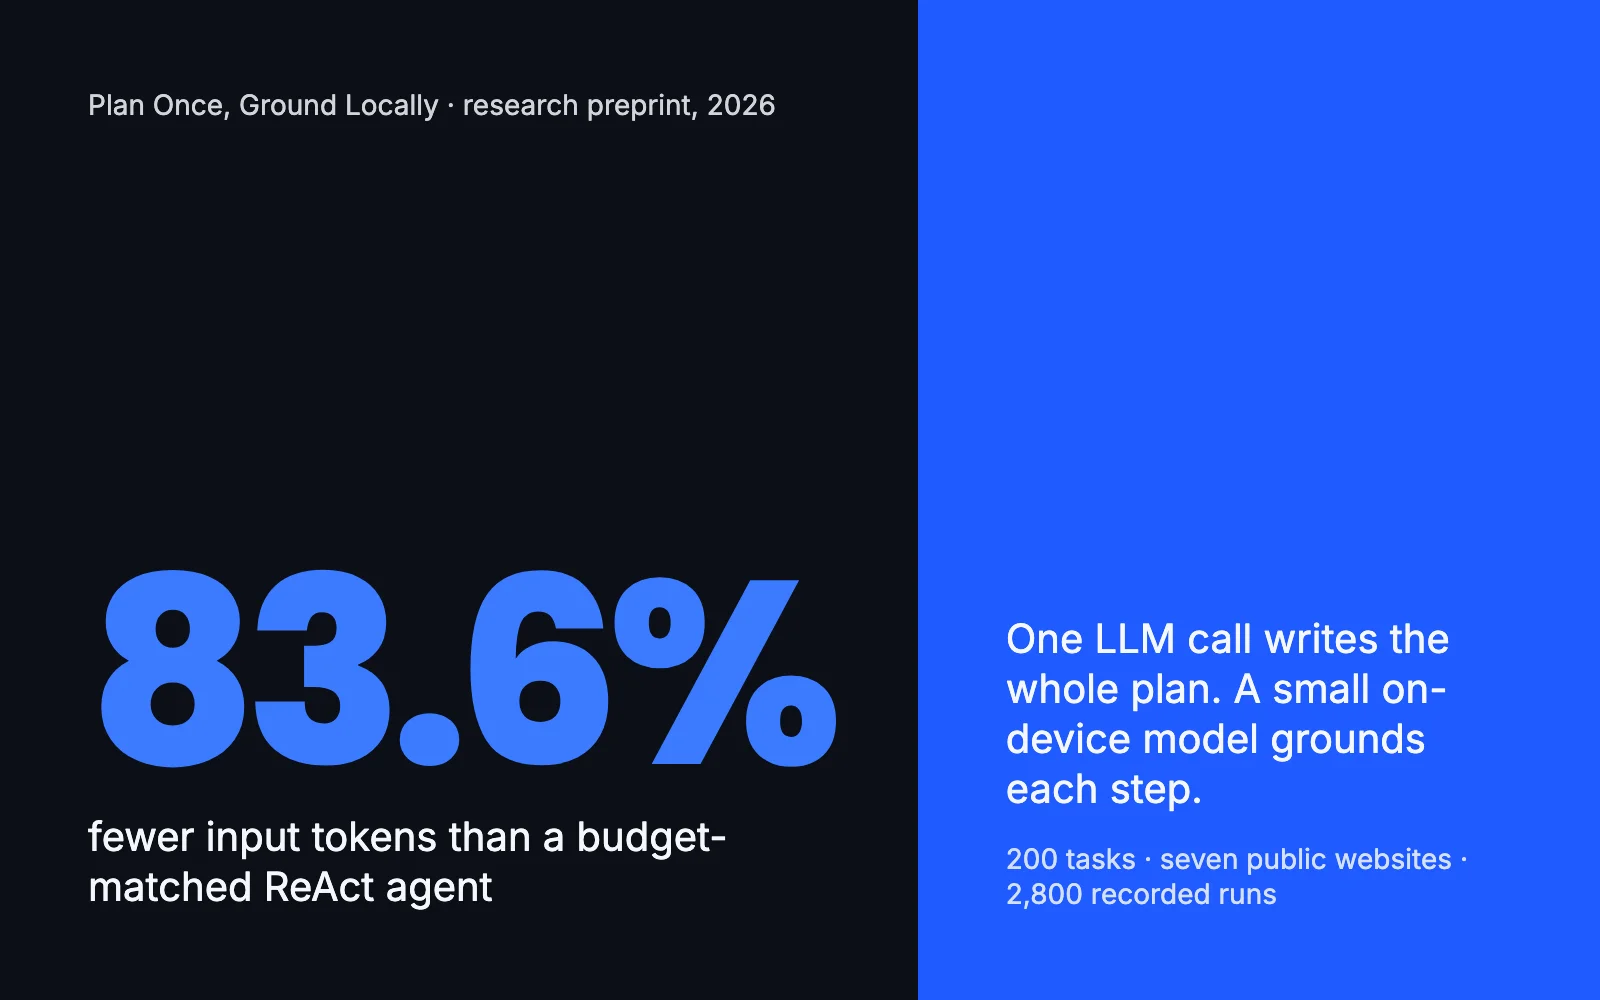
A plain-English explainer of our research preprint: web agents that write the whole plan in one LLM call and ground each step with a small on-device model match a budget-matched ReAct baseline on success with 83.6% fewer input tokens.
- ai agents
- research
- llm costs